
Introducing MJT
Micro-Judgement TuningTM
FTA's journey to specialist intelligence
Most AI is trained to copy one right answer. MJT teaches an open AI model to judge every option. Its debut application is FTA Mark-1, which beat three of the top four models on Kaggle's chess leaderboard (as of 12 Nov 2026).

From Experiment to Real-World Intelligence
FTA Global's proprietary AI training framework powers Mark-1, which won three chess match series against leading OpenAI and Google models. Now, we're applying MJT to build smarter, specialised intelligence for marketing.
What is MJT
Most AI learns to copy. MJT teaches it to judge.
The usual way to train an AI on a skill is to show it a question and the single right answer repeatedly until it copies. Micro-Judgement Tuning shows it every possible answer, each with a score from a strong teacher, so it learns why one option is better than another.
1. Score every option
A teacher grades every possible choice, not just the one right answer.
2. Keep each lesson small
Each lesson asks one simple thing: how good is this option?
3. Stack many small checks
At work, FTA's code asks hundreds of small questions and picks what holds up.
One MJT lesson, in chess
Tap each step to see what the model learns from one position.
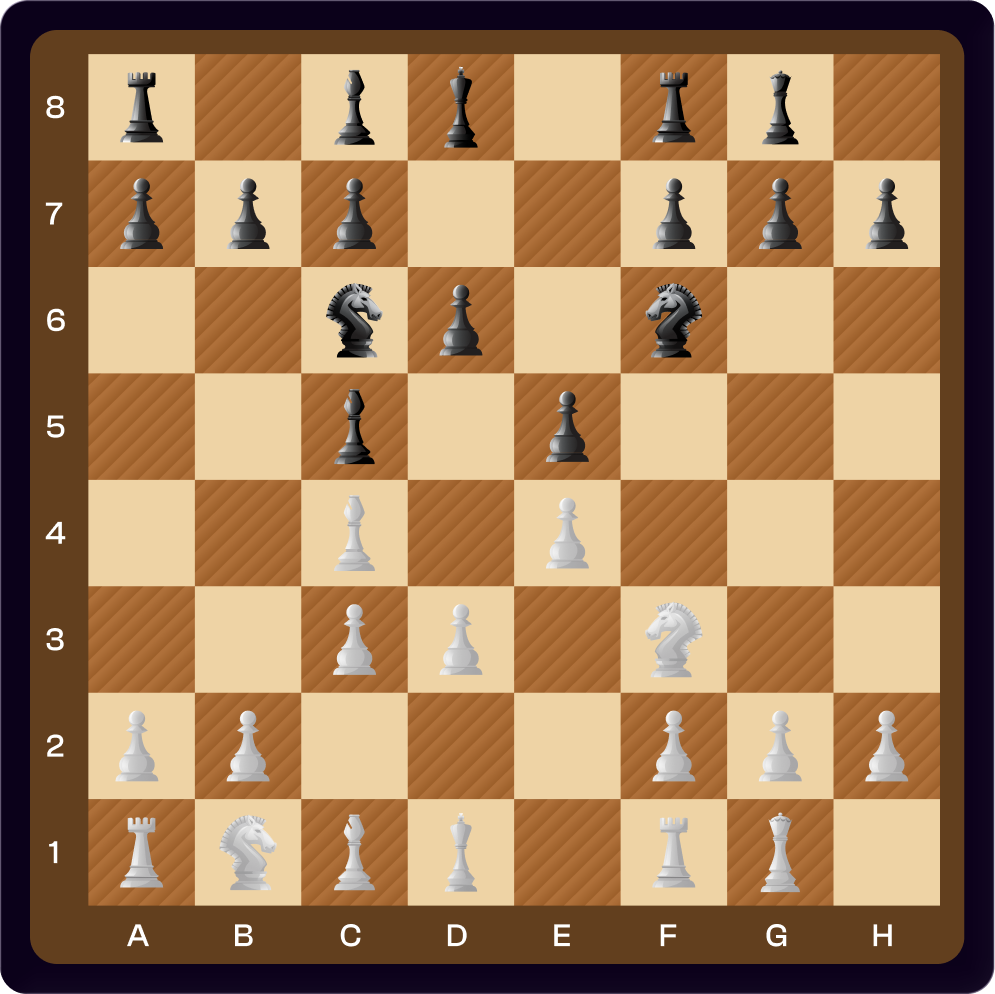
Step 1: a real position from a game. White to move.
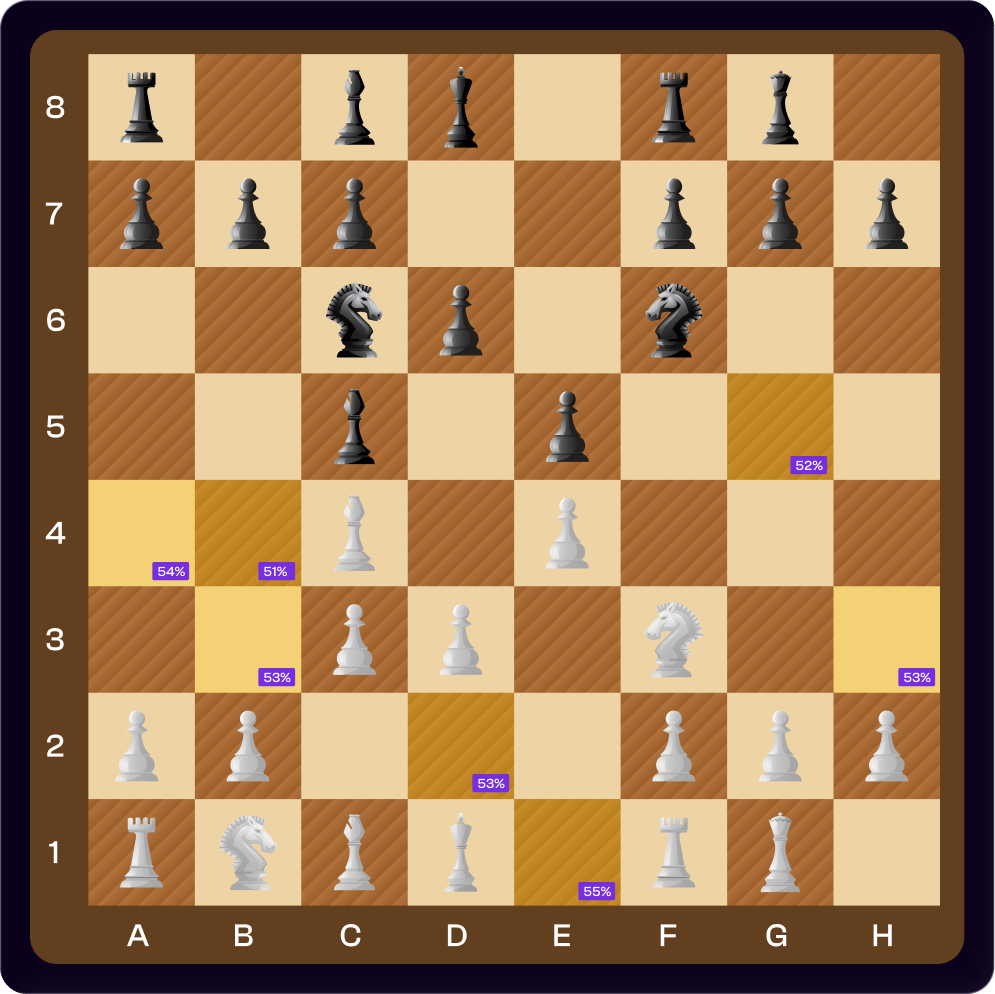
Step 2: every possible move gets a score (win %). Brighter = better.
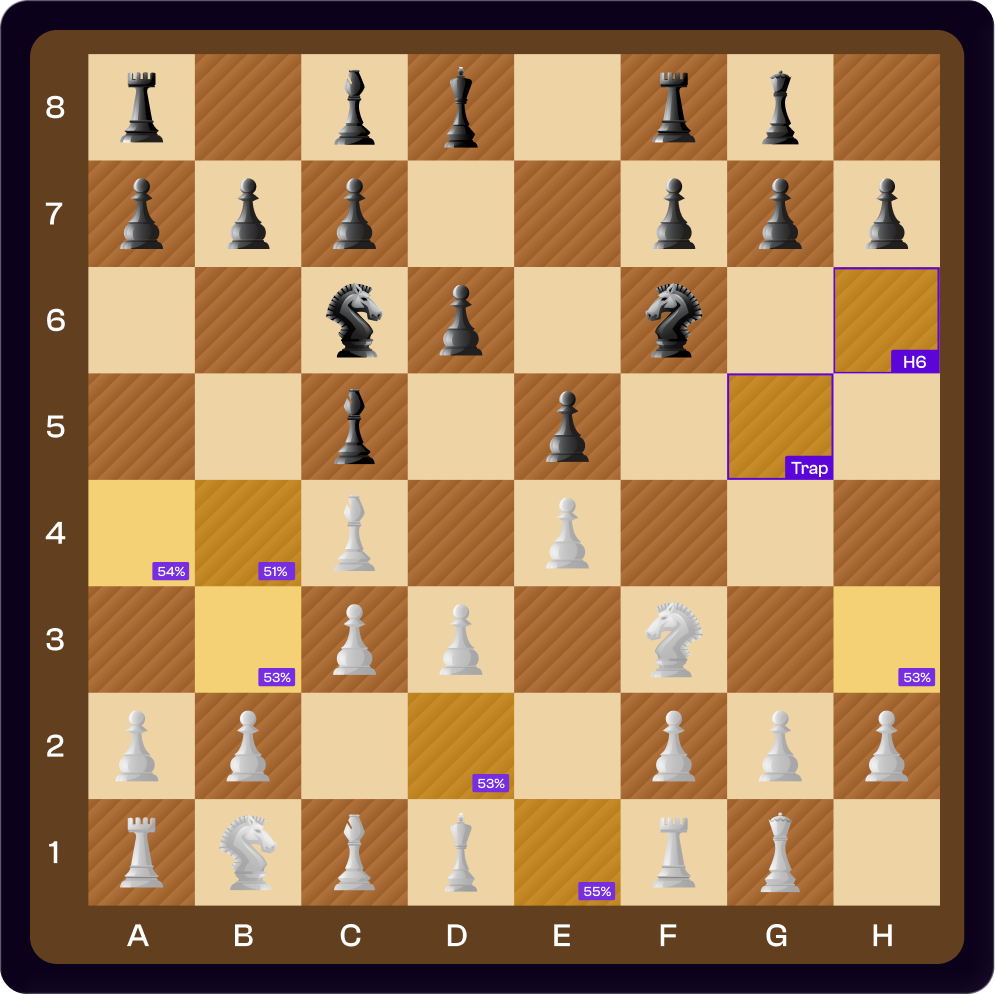
Step 3: the trap. Bg5 runs into h6.
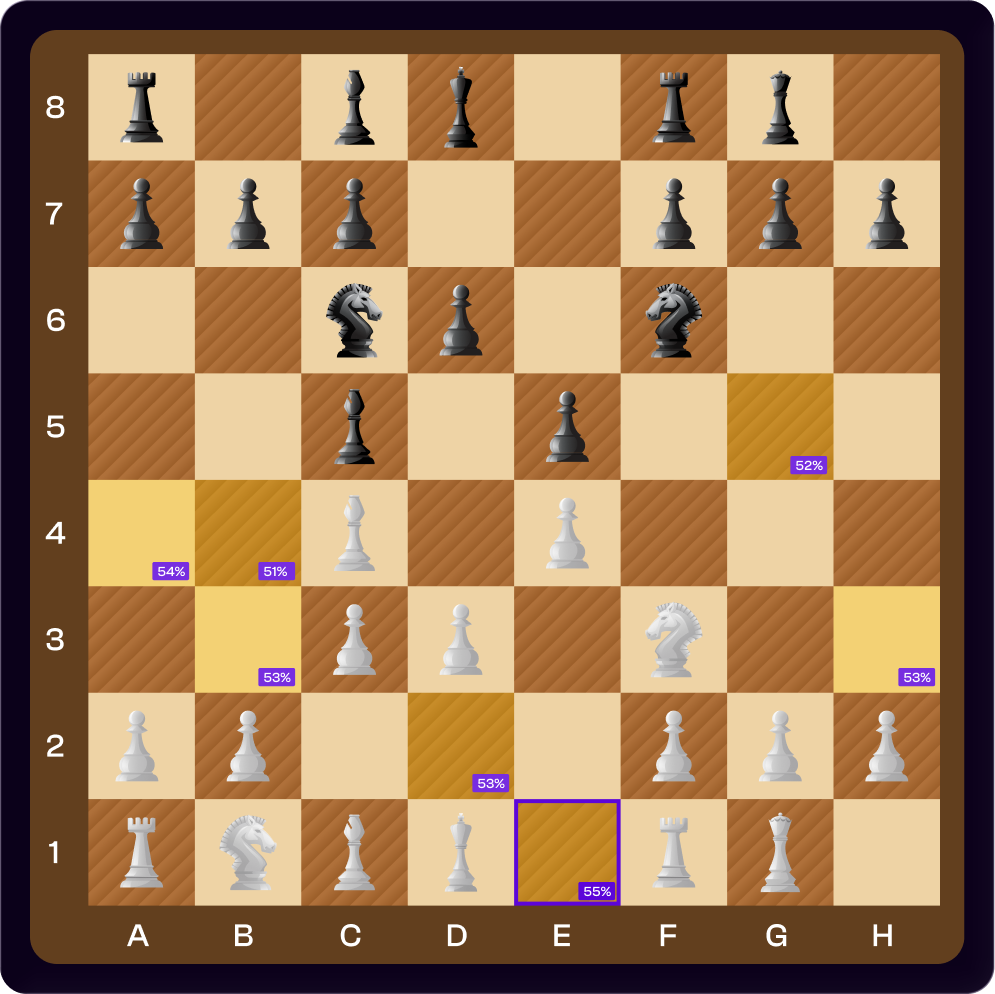
Step 4: the model picks Re1, the move that holds up best.
A chess computer marks the moves during training only, like a teacher. When Mark-1 plays, it is on its own.
How MJT thinks
One long thought, or hundreds of small judgements?
A big general model thinks through each move once, in one long private train of thought. An MJT model is trained to make one small judgement very well: "How good is this option?" At work, it makes hundreds of those judgements, checks the replies to them, then picks the option that still looks best. In chess, we call this part think-ahead.
Mark-1 took about a minute per move, Astra about the same, and the Gemini models took 13-14 seconds. No clock for either side, and every move’s time is published.
OpenAI's GPT-6 Astra
One long private chain
It thinks once, out of sight. You only see the final answer.
FTA Mark-1
Hundreds of small judgements
Each dot is one small judgement Mark-1 makes before it moves.
MJT’s debut: FTA Mark-1
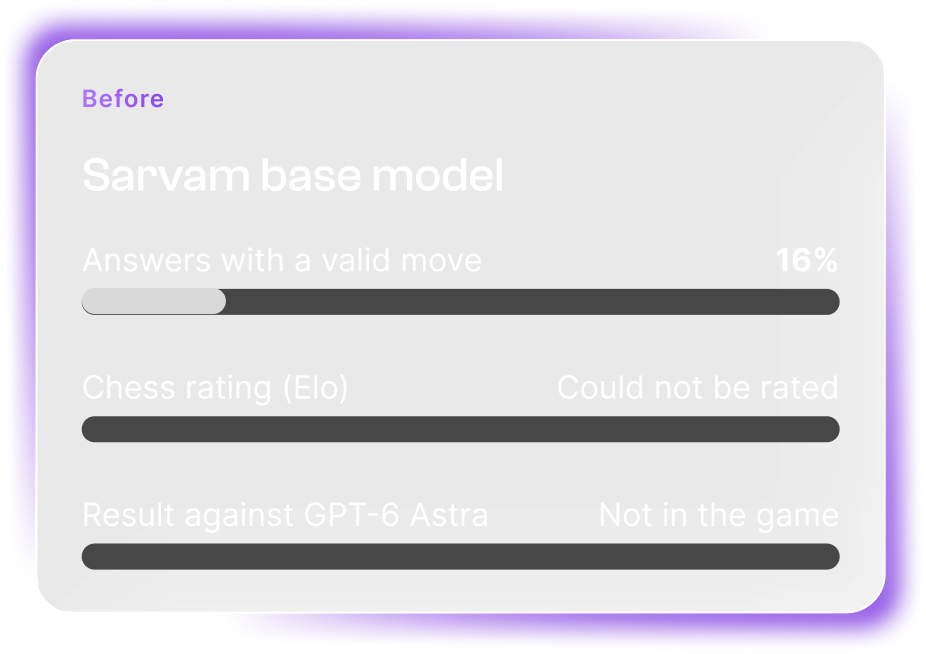
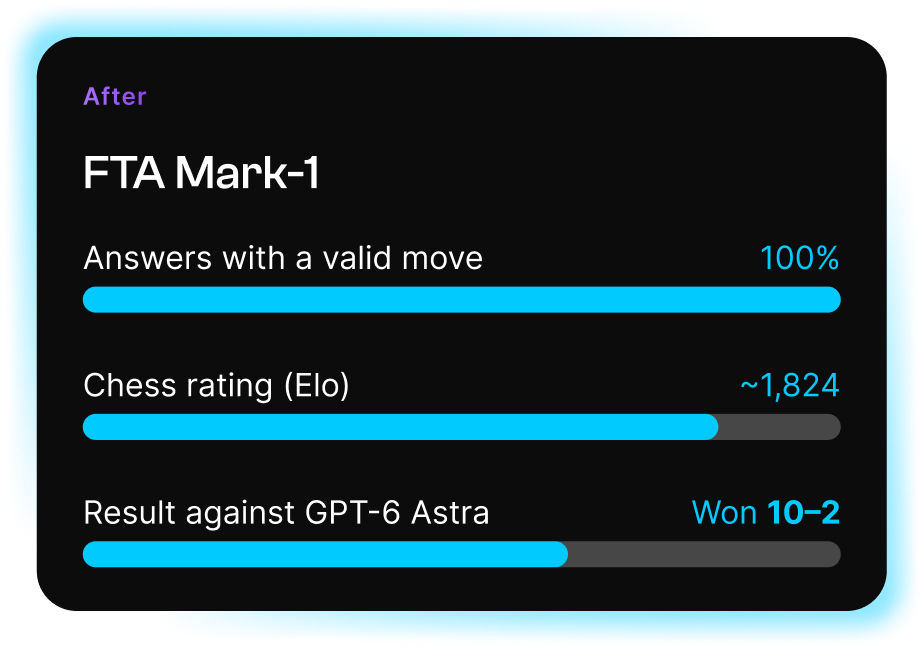
We took an open model that couldn't play chess. After MJT, it beat three of the top four models on Kaggle’s chess leaderboard (as of 12 Nov 2026).
Sarvam-30B is an open model made in India, but it was never taught chess. Out of the box, it played a legal move only 16% of the time. We trained it with MJT and called it FTA Mark-1. Same base model. We added a small trained layer and its own think-ahead.
The matches
Three matches. Three wins.
FTA Mark-1 played three of the top four models on Kaggle's chess leaderboard (as of 12 Nov 2026). Each match consisted of 12 games, six with each colour, played on 7 November 2026. Both sides used the same instructions and rule-checker, with no clock.
vs OpenAI's GPT-6 Astra
vs Google's Gemini 4 Argon
vs Google's Gemini 3.8 Flash
Every game is published. Logs and bills are available.
Mark-1 played with think-ahead, using only its own judgement. Each opponent played at its maker's default settings, the same as on Kaggle Game Arena. No chess computer helped either side. Everything was locked before the first move and timestamped before the results were announced.

Results
About 1,824 on the chess rating ladder
We rated Mark-1 the way chess players are rated: 24 games against Stockfish set to four strengths, under the same conditions Astra faced on its own ladder.
Strength rating (Elo)
Dot = best estimate. Line = likely range from the games played.
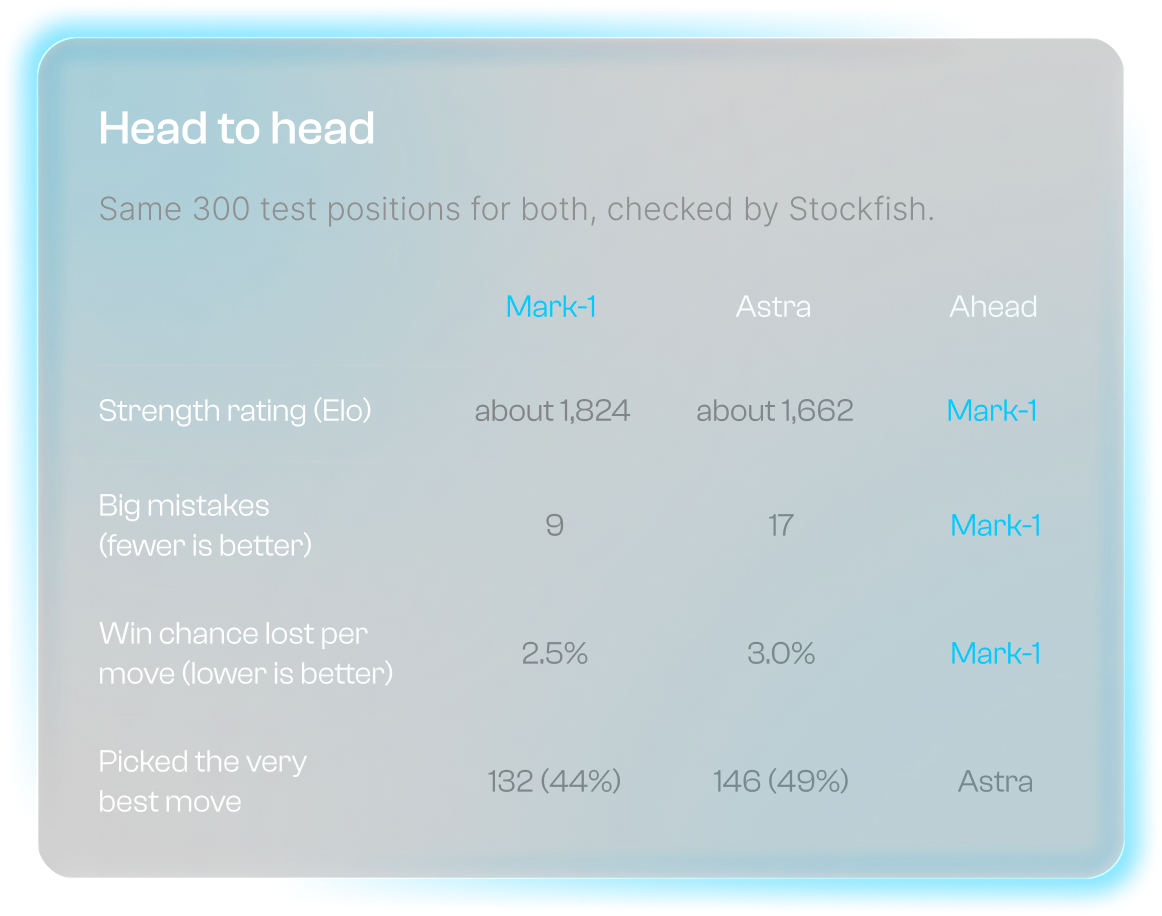
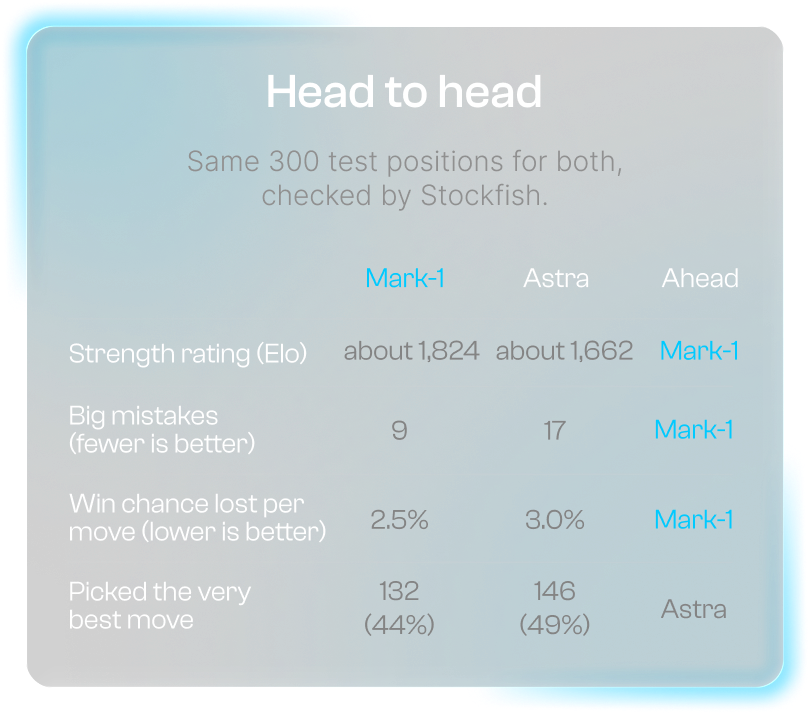
Head to head
Same 300 test positions for both, checked by Stockfish.
(fewer is better)
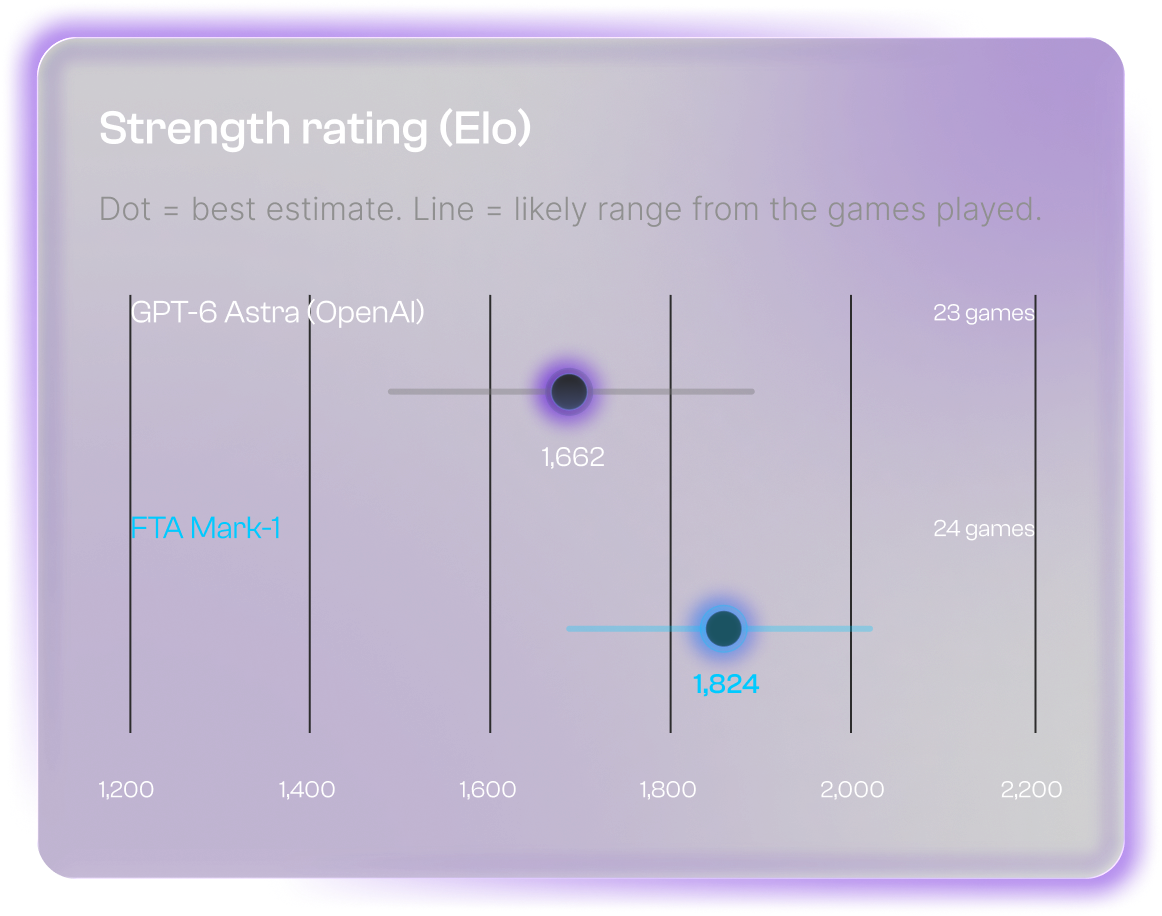
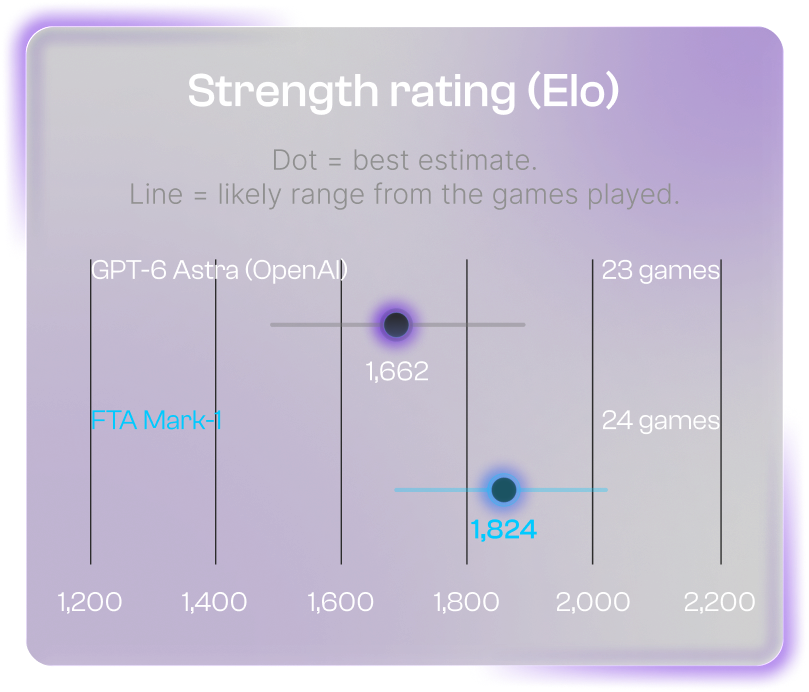
Ratings are measured against Stockfish's strength levels, not official FIDE ratings.
What Mark-1 taught us about MJT
A strong teacher matters more than lots of data.
The teacher is the whole game
With a strong teacher scoring every option, a general open model learned sharp judgement. A weak teacher gives a weak specialist.
More data stopped helping early
Past a point, adding positions did not move the rating. Better lessons and more time to think did.
Careful beats clever
Astra found the single best move a little more often. Mark-1 made far fewer big mistakes, and that is what won games.
1. Your coach
Built from your past results and from public case studies. It scores the options in front of your team.
2. Micro-Judgement Tuning™
The same method that made Mark-1. Learn from every option, not one answer.
3. Specialist intelligence for your team
Sharper calls for your team, every week. Your people stay in charge.
Specialist Intelligence
Others are building agents to replace marketers.
FTA builds the suit that makes them exceptional.
Micro-Judgement Tuning is our road towards specialist intelligence. Mark-1 is where it starts.
